Skip to content

Peiran Xu

Seeking 2027 full-time and internship opportunities

I also welcome research collaborations and new connections. Feel free to chat.

I am a fourth-year Ph.D. candidate at UCLA, where I am fortunate to be advised by Prof. Debiao Li. My research interests include LLM post-training, LLM agents, Agentic RL and AI for Healthcare.

I have also enjoyed my time as a research intern at Snowflake AI Research, Alibaba, and JHU. Before joining UCLA, I received my bachelor’s degree from Shanghai Jiao Tong University.

Experience

Research & engineering

Snowflake AI Research

-

Research Intern · Menlo Park, CA

Deep research agents that combine database querying and web search, from benchmark construction to SFT and reinforcement learning.

Alibaba

-

Research Intern · Sunnyvale, CA

Process rewards and reward normalization for long-horizon, non-verifiable agentic tasks.

Selected Publications

* Equal contribution
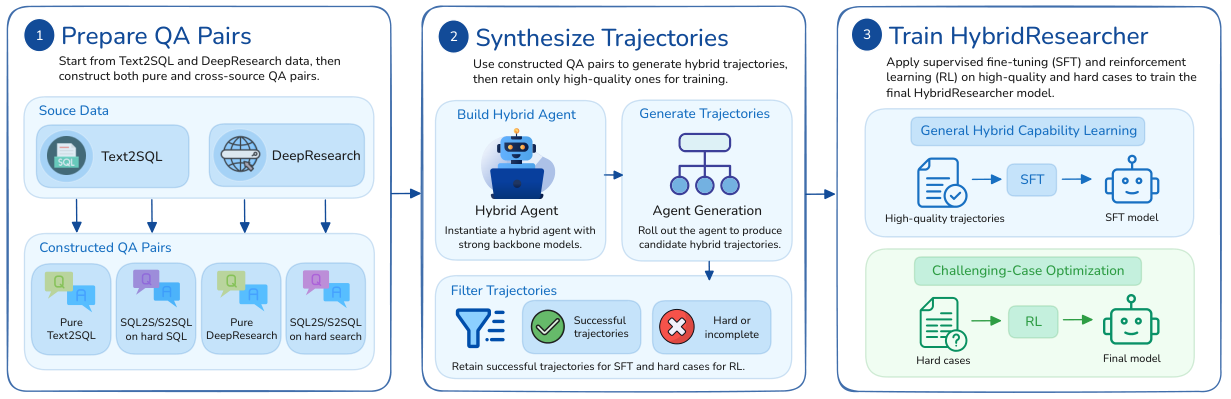
HybridResearcher pipeline for preparing QA pairs, synthesizing trajectories, and training with SFT and RL

2026 · Preprint

HybridResearcher: Bridging the Structured-Unstructured Boundary for Deep Research Agents.
Soyoung Yoon*, Peiran Xu*, Han Wang*, Ruofan Wu*, Xiaodong Yu*, Feng Yan, Mohit Bansal, Debiao Li, Seung-Won Hwang, Yuxiong He, Zhewei Yao

Training a 4B agent to reason across SQL and web search through synthetic data, SFT, and reinforcement learning.

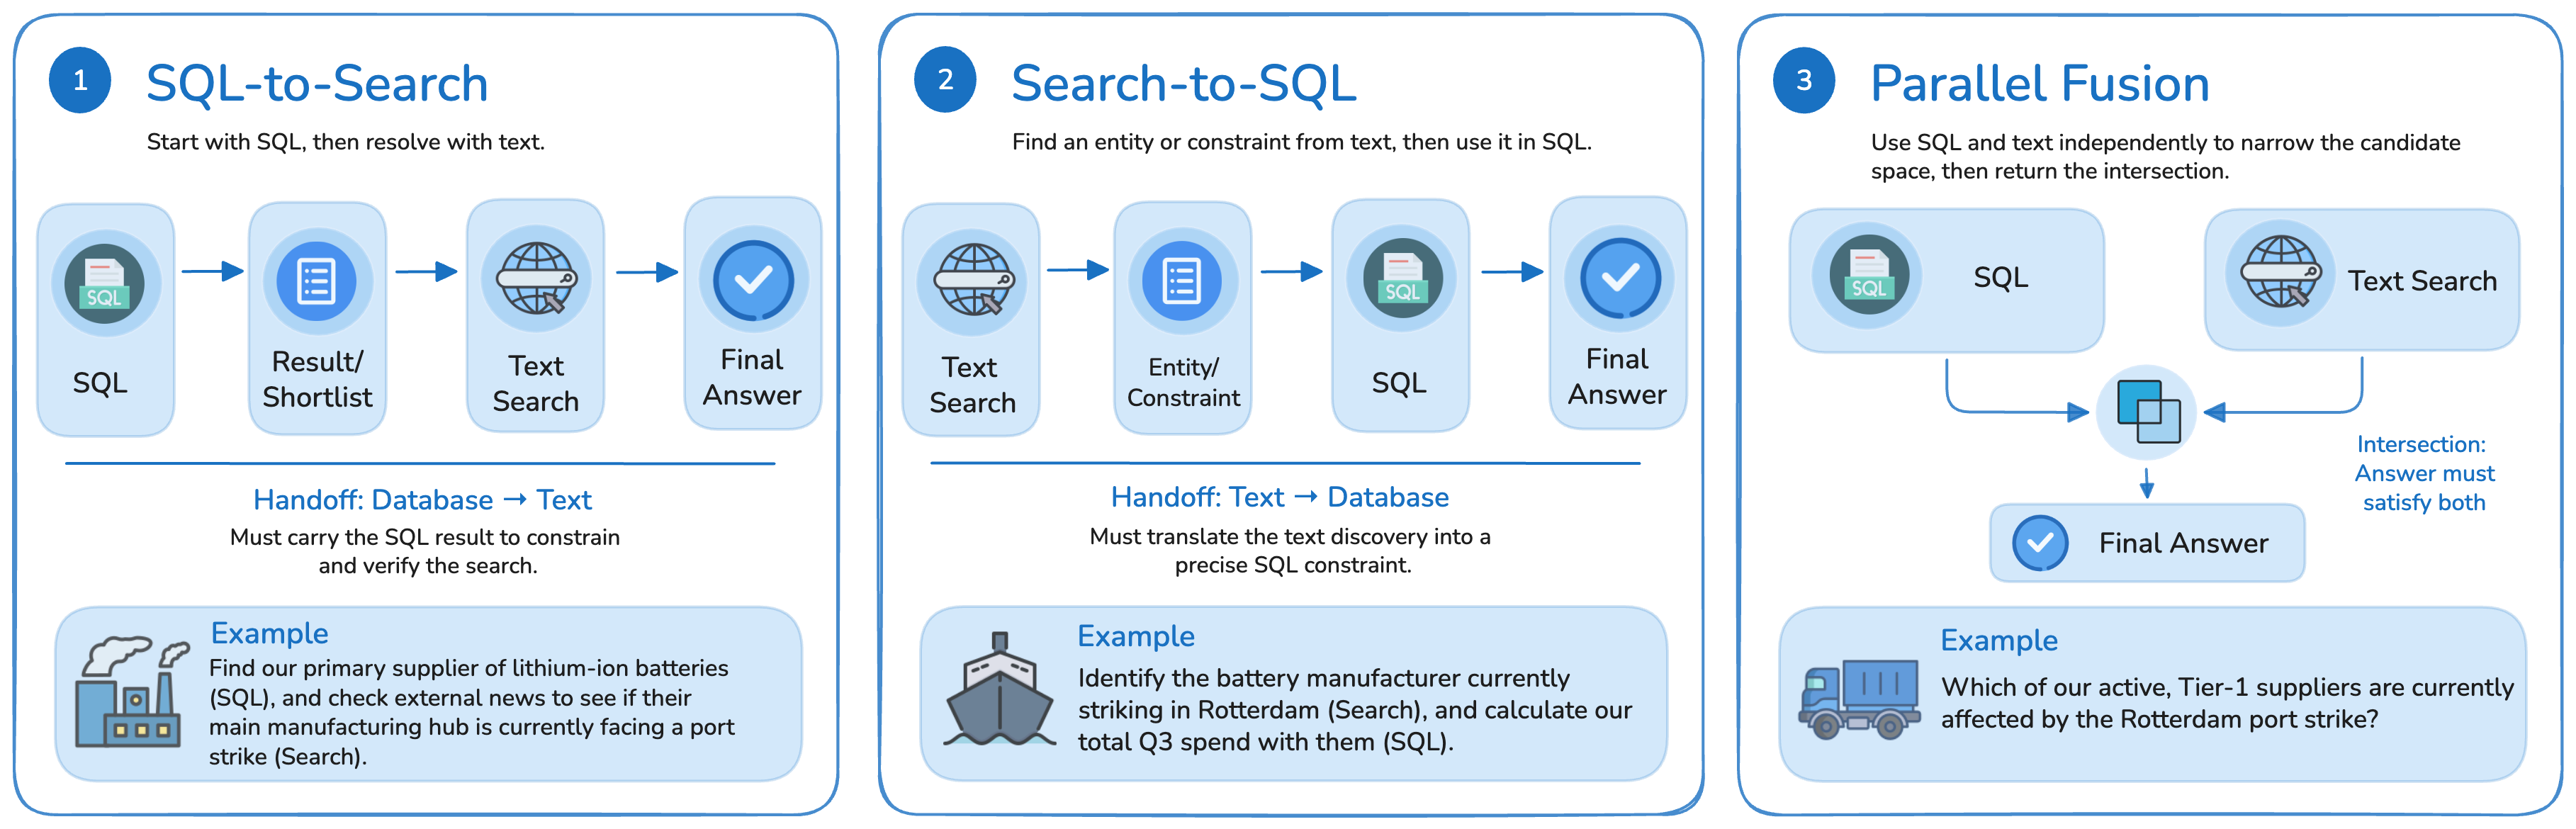
SQL-to-search, search-to-SQL, and parallel reasoning patterns in HybridDeepResearch

2026 · Preprint

Benchmarking Hybrid Deep Research Across Database Querying and Web Search.

Ruofan Wu*, Peiran Xu*, Xiaolong Li*, Fan Shu*, Soyoung Yoon, Yite Wang, Xiaodong Yu, Boyi Liu, Feng Yan, Debiao Li, Yuxiong He, Zhewei Yao

Evaluating whether agents can combine structured database records with evidence from the open web.

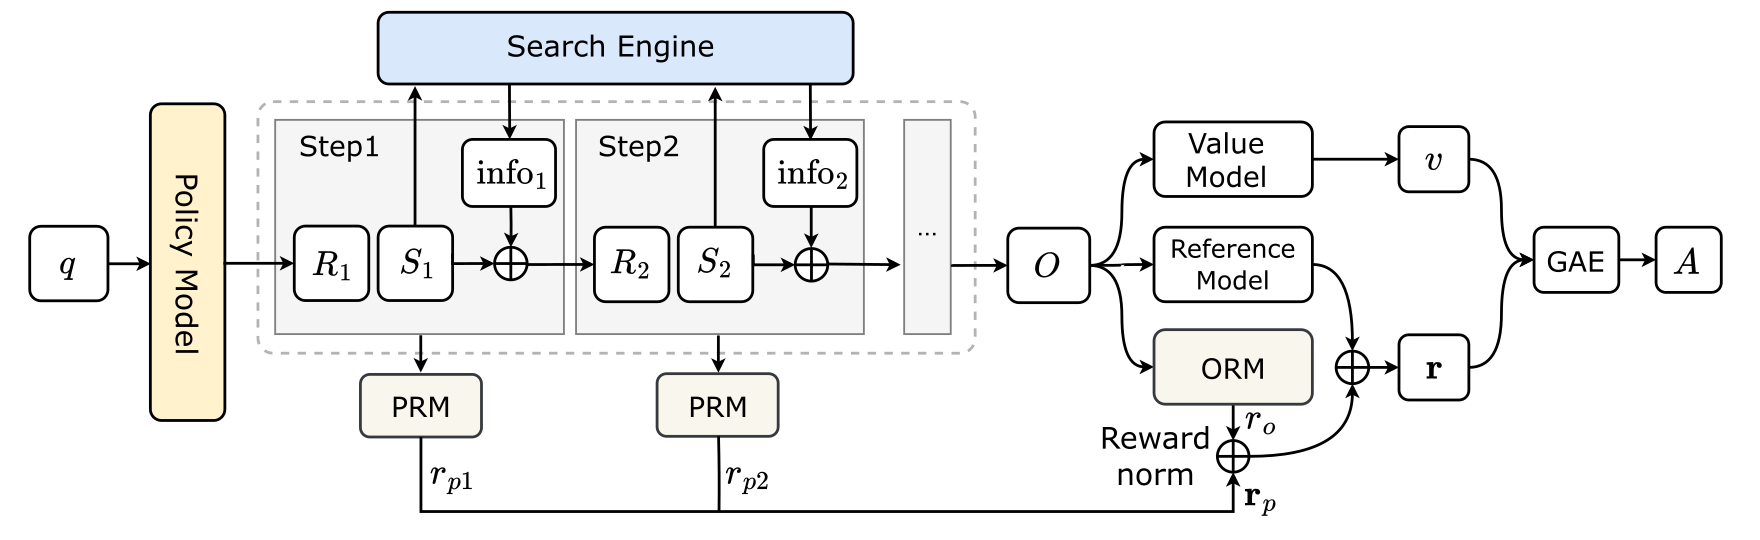
Overview of PPR rollout with process and outcome reward models

2025 · Preprint

Hybrid Reward Normalization for Process-supervised Non-verifiable Agentic Tasks.

Peiran Xu*, Zhuohao Li*, Xiaoying Xing, Guannan Zhang, Debiao Li, Kunyu Shi

Aligning dense process rewards with final task outcomes for more stable agent reinforcement learning.

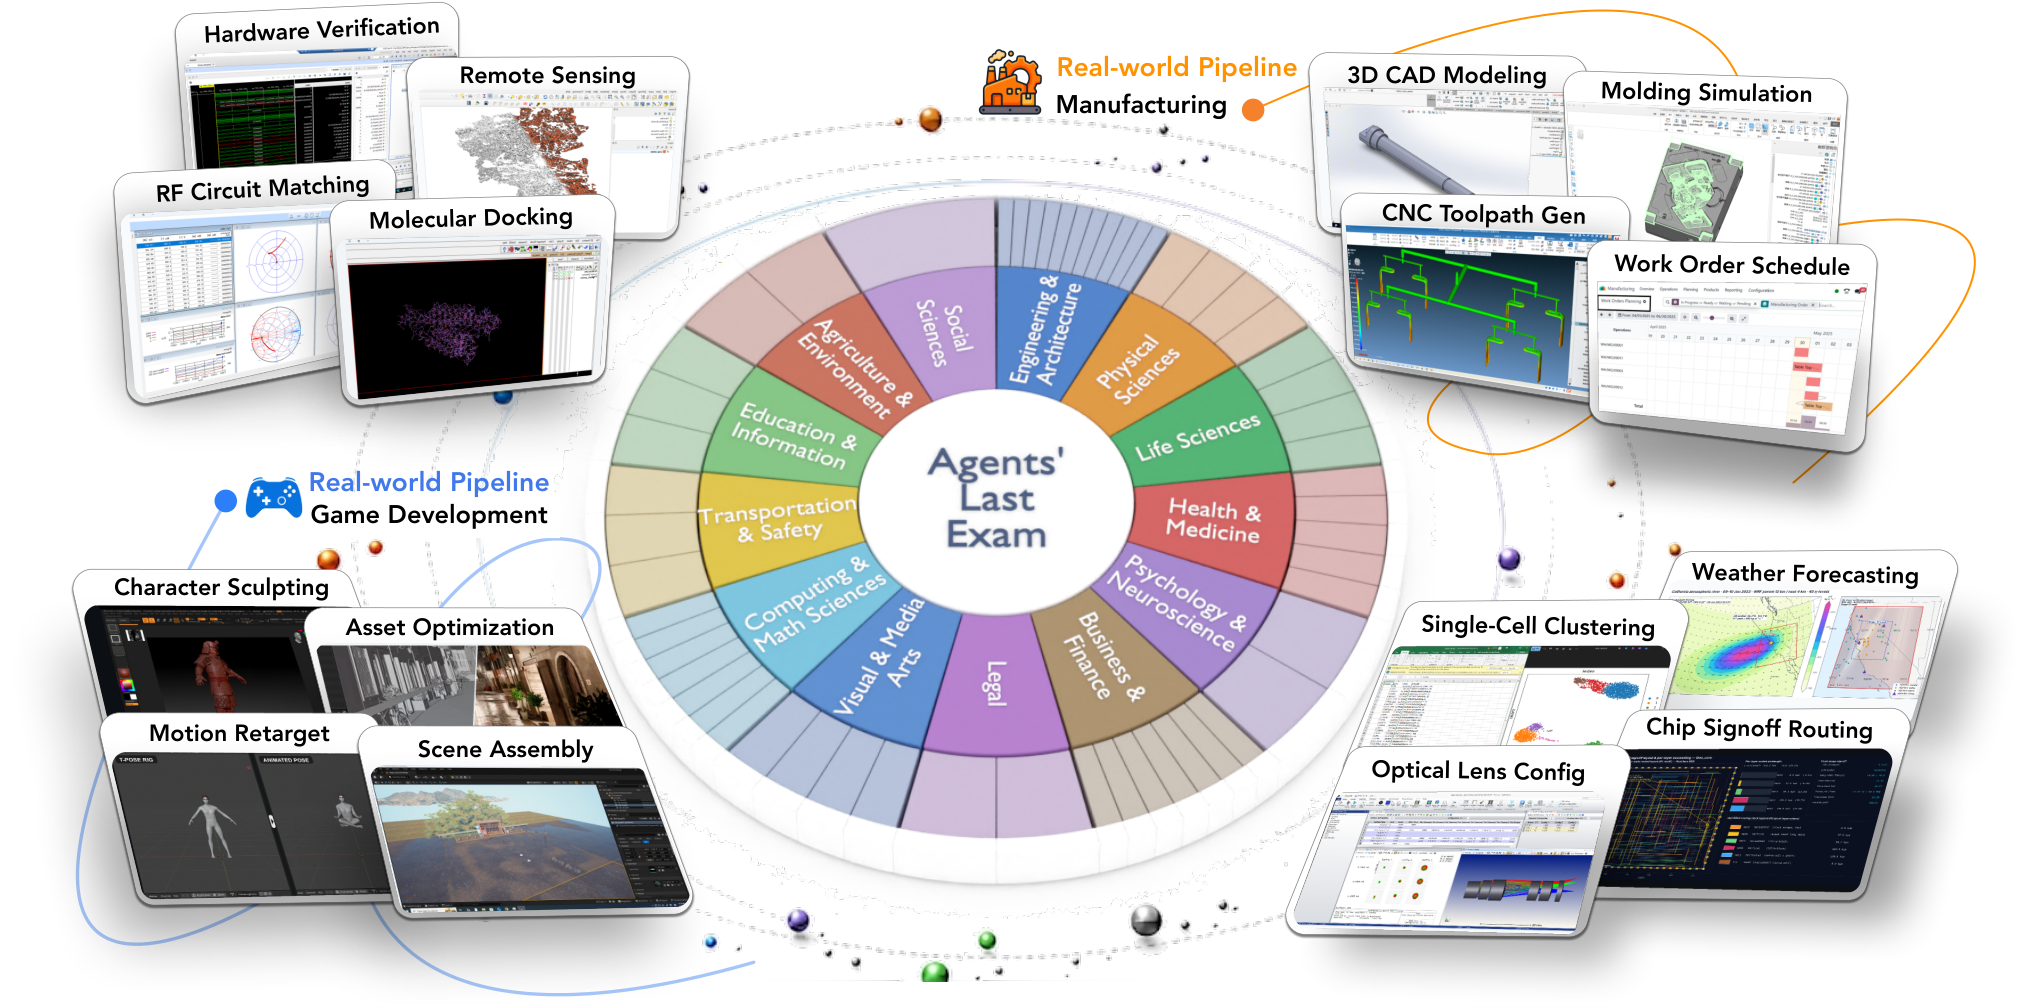
Professional task taxonomy and example workflows in Agents' Last Exam

NeurIPS 2026

Agents' Last Exam.

Yiyou Sun, Xinyang Han, Weichen Zhang, …, Peiran Xu, et al.

A benchmark of long-horizon professional workflows with verifiable outcomes.

AtlasGS shared Gaussian geometry framework for multi-contrast MRI harmonization

MICCAI 2026

AtlasGS: Brain MRI Spatial Resolution Harmonization With Shared Gaussian Geometry.

Yifan Gao, Peiran Xu, Yimeng He, Haoran Li, Ziyang Long, Yufeng Wang, Ju Dong Yang, Debiao Li

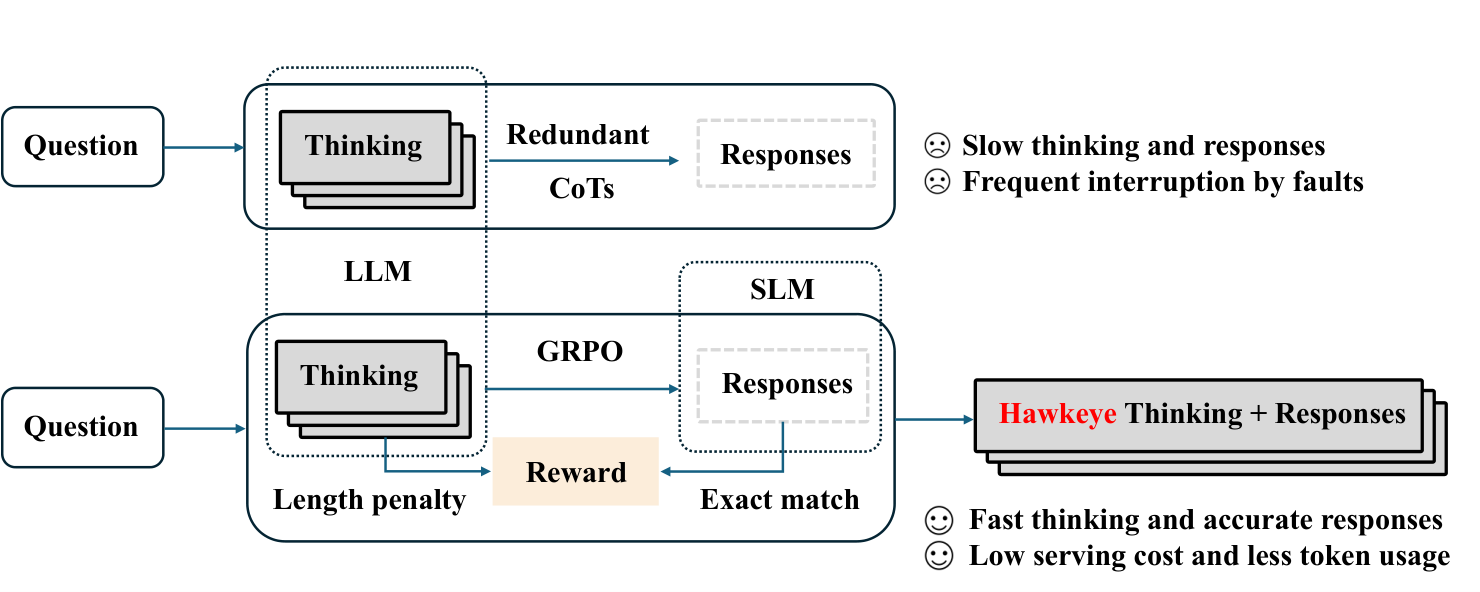
Hawkeye model collaboration framework compared with standard reasoning pipelines

COLM 2025

Hawkeye: Model Collaboration for Efficient Reasoning.

Jianshu She*, Zhuohao Li*, Zhemin Huang, Qi Li, Peiran Xu, Haonan Li, Qirong Ho

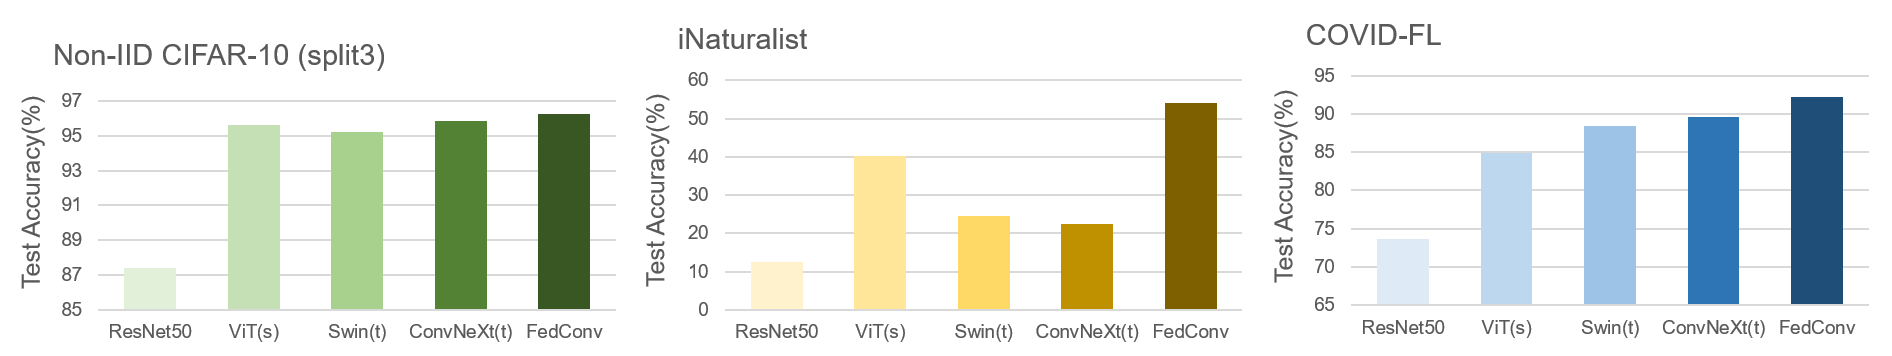
FedConv performance comparison on CIFAR-10, iNaturalist, and COVID-FL

TMLR 2024

FedConv: Enhancing Convolutional Neural Networks for Handling Data Heterogeneity in Federated Learning

Peiran Xu*, Zeyu Wang*, Jieru Mei, Liangqiong Qu, Alan Yuille, Cihang Xie, Yuyin Zhou